Customer Service KPIs That Actually Predict Churn

Updated 21 October 2026: every statistic re-checked against its original source and dated. Several figures that circulate widely (and that an earlier version of this post repeated) turned out to be wrong or untraceable, so they're gone.
Customer service KPIs come in two kinds: the ones that measure how busy your team is, and the ones that tell you whether customers will stay. The second kind is shorter than you'd think. Customer effort, first contact resolution, repeat contacts and resolution time by complexity, plus one business metric. Five numbers, read properly, beat fifteen read badly.
Your dashboard probably has fifteen numbers on it. Tickets closed per hour. Average handle time. Agent utilisation. CSAT split six ways. The charts look great.
And none of them warned you about the customer who left last month. Three support conversations in six weeks, each one a little shorter-tempered than the last, each one closed on time. Then a cancellation email.
The dashboard said everything was fine. It was counting the work, and nobody had asked it what the work did for the customer.
What makes a customer service KPI worth tracking?#
A customer service KPI is worth tracking if it can't improve while customers get angrier, and if you'd do something different when it moves by 10%. Metrics that pass both tests measure outcomes. Metrics that fail them measure activity: useful for staffing, misleading as a scorecard. (A KPI is just a metric you've decided to steer by, so the test is what promotes one to the other.)
Take tickets closed per day. Up 15%? Maybe the team worked harder. Maybe volume spiked, or you hired, or the product broke in a new way. The number can't tell you which, and it can't tell you whether anyone's problem got fixed or the ticket just left the queue.
Now take repeat contact rate: how often a customer comes back about the same issue. When it rises, it means one thing. Resolutions aren't sticking. And it points straight at what to check: answer quality, training, agents rushing closures to hit a speed target.
See the difference?
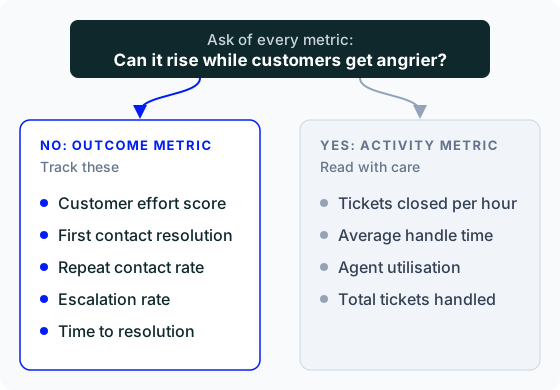
Run the usual metrics through that test and they sort like this, each with the trap I'd watch for.
| Metric | What it tells you | How to calculate it | The trap |
|---|---|---|---|
| Customer effort score (CES) | Whether getting help was easy. In CEB's research it predicted loyalty better than CSAT or NPS | Answers of 5 to 7 on a 7-point scale ÷ all answers × 100 | Comparing effort across issue types that should take different effort |
| First contact resolution (FCR) | Whether issues get fixed in one go | Issues sorted on first contact ÷ eligible issues × 100 | Definitions vary so much that benchmarks rarely compare |
| Repeat contact rate | Whether "resolved" really meant resolved | Customers back about the same issue within 7 days ÷ resolved issues × 100 | Only counting linked reopens, missing new tickets about the old problem |
| Time to resolution | How long customers wait for a fix | Median hours from first message to resolution, per complexity tier | Using the mean, so one ugly ticket moves the whole number |
| Escalation rate | How often the first contact can't settle it | Escalated conversations ÷ all conversations × 100 | Treating low as good, when it can mean agents guessing |
| CSAT | Whether the customer liked the interaction | Satisfied answers ÷ all answers × 100 | Averages hide the unhappy tail, and low response rates skew it |
| Average handle time | How long an agent spends per ticket | Total handling time ÷ tickets handled | The easiest metric to game, by rushing or closing early |
| Tickets closed | How much work moved | A count | Rises when things go wrong, too |
Vanity Metrics That Mislead#
Vanity metrics are the ones that look healthy in a report while customers drift away: total tickets handled, average handle time on its own, agent utilisation pushed towards 100%, and an unsegmented CSAT average. None of them is useless. Each one is overweighted, and each has a better number to track in its place.
Is total tickets handled a useful KPI?#
Not as a score. A high ticket count feels like a busy, productive team, but tickets are a cost. More of them usually means more customer friction. A team handling 10,000 tickets a month isn't doing better than one handling 5,000 if the smaller number came from better self-service, a clearer product or proactive emails.
The goal is fewer tickets, and volume follows patterns you can see coming. Post-holiday returns land in January. Billing questions cluster around the end of the month. Launches and campaigns bring their own waves. If Black Friday "unexpectedly" doubled your volume, the calendar told you and nobody read it.
Track instead: contact rate per customer, meaning tickets divided by active customers. A 20% rise in tickets with 25% more customers is healthy. A 20% rise with a flat customer base means something in the product or your communication has gone wrong.
Why is average handle time misleading on its own?#
Because it's the most gamed number in support. Measure agents on speed and they'll give you speed: rushed answers, half-fixes, customers back tomorrow and angrier. A four-minute AHT means nothing if half those tickets reopen within a week. You haven't saved time. You've doubled the work and taught customers to double-check you.
The gaming is predictable once you've seen it. Agents send "I'm looking into this" to stop the clock. They close a ticket early and let the reply come back as a "new" one, which resets the timer. They cherry-pick the easy tickets and leave the hard ones for colleagues. None of it shows on the AHT chart. All of it shows in reopen rates, if you look.
Track instead: handle time by complexity tier, next to the reopen rate. Three tiers is enough. Simple (password resets, tracking checks), moderate (billing questions, product questions) and complex (technical faults, escalations). Give each its own target. Holding a tricky integration problem and a shipping check to the same eight-minute goal just pushes people to cut corners on the hard ones.
Should agent utilisation be close to 100%?#
No. Utilisation near 100% looks efficient and works like a debt. A team at 95% has no room for a volume spike, no time for coaching, and no breathing space between angry customers... and your best agents notice before you do.
Nobody has a magic number here. ICMI, the contact centre trade body, says plainly that "one size is not going to fit all". In practice a lot of workforce planners keep occupancy somewhere in the 70s to mid-80s so there's slack for spikes and training. Treat that as a rule of thumb, and watch the signals that matter more: agent satisfaction, sick days, and who's quietly updating their CV. If you want the longer version, our post on scaling support without burning out the team covers it.
What's wrong with an average CSAT score?#
It hides the customers you're about to lose. An average of 4.2 out of 5 can be 90% of customers at 4.5 and above and 10% at 1.5. That bottom tenth is your churn list, and it barely moves the average.
Two other things decide whether your CSAT means anything. Timing first: a survey sent straight away captures relief at getting an answer, while one sent a day later captures whether the answer worked. Neither is wrong, but they measure different things, so don't compare them. Then response rate. A 4.5 from 15% of customers is less trustworthy than a 4.0 from 40%, because the people who don't answer skew neutral or negative.
Track instead: the CSAT distribution as a histogram, split by issue type, channel and agent. Peaks at 5 and 1 tell a very different story from a hump around 4. The first is a polarised experience worth digging into. The second is steady mediocrity.
Actionable KPIs That Predict Churn#
Actionable KPIs are the ones that move before customers leave and point at a specific fix. Customer effort score, first contact resolution, repeat contact rate, time to resolution by complexity and escalation rate all qualify. But a churn predictor measured badly is just another vanity metric, so how you measure each one matters as much as which ones you pick.
Customer Effort Score (CES)#
Customer effort score asks how easy it was to get an issue sorted, usually as "[Company] made it easy to handle my issue" on a 1 to 7 scale. It's the KPI with the strongest research behind it as a loyalty predictor, and the one most dashboards still don't have.
The research is CEB's (CEB is now part of Gartner), published in Harvard Business Review in 2010 as "Stop Trying to Delight Your Customers". It surveyed more than 75,000 people. Of the customers who reported low effort, 94% intended to buy again and 88% said they'd spend more. Of those who had a hard time, 81% said they'd spread negative word of mouth. And the line that should be on every support lead's wall: "Customers are four times more likely to leave a service interaction disloyal than loyal." On prediction, the authors found CSAT "a poor predictor" of loyalty, NPS better, and CES "outperformed both" in service interactions (HBR, July 2010).
You'll see a "96% of high-effort customers become disloyal" figure quoted everywhere. It isn't in the HBR article, and I couldn't find it on any Gartner or CEB page, so it isn't here.
Effort is relative, though. Thirty minutes setting up new software feels fine. Thirty minutes finding out where a parcel is feels like a stolen afternoon. So compare CES within one type of issue, never across the whole queue. On the usual percentage method, 70 to 80% answering 5 or more is decent and 90% plus is excellent, as a rule of thumb rather than a published benchmark.
The biggest effort killer is repetition. Zendesk's CX Trends 2026 report found 74% of consumers are frustrated when they have to repeat information (Zendesk CX Trends 2026, November 2025). Asking for an order number they already gave. Making them retell the story after moving from chat to email. Pull your lowest-scoring conversations and read them. You'll find the problem at a handoff almost every time.
First Contact Resolution Rate (FCR)#
First contact resolution is the share of issues sorted on the first contact with no follow-up. It's a strong loyalty signal and a terrible benchmark, because nobody measures it the same way.
Some teams count a ticket as resolved when an agent closes it. Others wait for the customer to confirm. Some check for a repeat contact over 24 hours, others over seven days. An 85% on one definition and a 70% on another can describe the same team. You might be celebrating or panicking over numbers that can't be compared.
So if you benchmark, know whose method you're borrowing. SQM Group, which surveys customers within one business day of the contact, puts the average FCR at 71% in its 2026 update, with 70 to 79% counted as good. "World-class FCR rate is 80% or higher, and only 5% of call centers can achieve it." Rates run from roughly 40% to 91%. Retail has the highest average at 77% and tech support is at 64% (SQM Group, updated 20 August 2026). SQM also says every 1% gain in FCR brings a 1% drop in operating costs, a 1% rise in customer satisfaction and a 2.5% rise in employee satisfaction. That's SQM's correlation from its own surveys, so I'd trust the direction more than the decimal places.
One caveat. Some issues can't be fixed in one contact: backorders, bugs waiting on engineering, disputes that need a manager. Leave those out and track FCR on eligible issues only. Otherwise you teach agents to give a wrong answer rather than escalate.
Repeat Contact Rate#
Repeat contact rate is the share of resolved issues where the customer comes back about the same thing within a set window. It's the most honest check on every other number on your dashboard. Of the pages ranking for customer service KPIs in October 2026, one mentions it, in a single line.
The reason it matters: "closed" in your helpdesk and "resolved" for the customer are different events. Agents close when they've sent what they believe is a complete answer. Customers consider it resolved when the problem's gone. A shipping delay closed with "your package is on its way" isn't resolved if the package is lost. A refund request closed with "we've started your refund" isn't resolved until the money lands.
So track reopens, but also track shadow reopens: new tickets from the same customer within seven days about the same issue that nobody linked to the old one. Most helpdesks can match them on customer ID and a few keywords. Manual tagging misses a lot of them, which is why the linking should be automatic where you can make it so.
As a rule of thumb, a repeat contact rate above about 20% deserves a proper look. Split it by agent to find premature closures, by issue type to find what's systematically under-fixed, and by channel to find where the communication breaks. The same check is what turns a flattering containment rate into an honest one, which matters as soon as a bot is answering part of your queue.
Time to Resolution by Complexity#
Time to resolution is how long a customer waits from first message to a fix. Measured as one average across everything, it tells you very little. Split by complexity and measured as a median, it's one of the better early warnings you have.
Raw averages blend wildly different tickets. "Where's my order?" should take minutes. An integration fault might take days. And the mean lets outliers run the show: one 30-day ticket (engineering involved, customer on holiday halfway through) can drag the average up by hours while 99 others closed quickly.
Use the median. If your mean is 18 hours and your median is 3, you don't have a speed problem. You have an outlier problem, and the fix is an exception process for the stuck ones. Pushing the whole team to go faster won't touch it. Then look at the 90th percentile, because that's what your most frustrated customers are living through.
Set a median target per tier and track the share of each tier that meets it. Our own starting points, which you should tune: simple under 10 minutes, moderate under 4 hours, complex under 48 hours. Complex tickets running late usually means a training or escalation problem. Simple ones running late means a queue or process problem.
Escalation Rate#
Escalation rate is the share of conversations passed up a level, to a specialist, a supervisor or, from a bot, to a person. Low isn't automatically good, and the escalation management rules behind the number matter more than the number.
If agents avoid escalating because it hurts their stats or the supervisor is unapproachable, they'll handle things beyond their authority. Wrong information, promises they can't keep, fixes that make a bigger mess later. There isn't one good rate either. A team supporting complex software will escalate far more than one handling shipping and returns, and that's fine.
What does tell you something is what happens after the handoff. If the supervisor approves what the frontline proposed nine times out of ten, you're wasting their time on rubber stamps, so give the frontline (or your AI's playbook) that authority. If the outcomes keep changing, your training or policy isn't clear enough. And if they keep changing on refund amounts specifically? Your refund policy is probably vague or applied unevenly.
Is NPS worth tracking for support?#
Only if you segment it by support interaction. Company-wide NPS moves with price, product and a dozen other things, so it can't tell you much about support. NPS asked straight after a support conversation, and compared with your company baseline, can.
If support conversations drag NPS below baseline, support is a retention problem. If they lift it, your team is an advantage worth investing in, and you've got the numbers to say so.
What do customer service dashboards miss?#
Dashboards only see customers who did something: opened a ticket, answered a survey, called. They miss the customers who give up quietly, they inherit every flaw in your ticket tagging, and they invite comparisons between channels that don't compare. And quality scores add their own error on top.
What about customers who never contact you?#
They're the most dangerous group, because they generate no data at all. A customer who hits a problem, can't find help and leaves doesn't touch your ticket volume or your CSAT. You find out months later in the churn numbers.
Watch for friction without contact instead. Abandoned carts after a visit to the help pages. Help articles with high bounce rates. Repeated failed logins with no ticket after them. Fair warning: each of these has other causes (price, a changed mind, a bug that has nothing to do with support), so you can't pin them on support directly. But if those patterns line up with later churn, support access is worth a closer look.
Can you trust your ticket tags?#
Mostly not. Every breakdown by issue type is only as good as the tagging under it, and most tagging is poor. Agents tag inconsistently. Categories go stale as the product changes. "Other" quietly becomes the biggest category. Then leadership reads "Shipping: 35%" and makes decisions on noise.
Audit it every quarter. Pull 50 random tickets from each big category and check the tags. If fewer than about 85% are right, don't trust category-level analysis. If "Other" is more than about a tenth of the queue, your categories need work. AI tagging from the ticket text can help with consistency, but check it the same way before you treat it as truth.
Should you compare CSAT across channels?#
Not without controlling for the issue. "Phone CSAT is 4.5, chat is 3.8, fix chat" is the classic mistake. Customers pick the channel to suit the problem. They ring when they're worried or the problem's messy. They chat for quick, transactional things. They email when they want a written record. Compare channels overall and you're mostly comparing moods.
Compare phone and chat for the same issue type (shipping against shipping) and you've got a fair test. Also watch channel switching. A customer who starts on chat and ends up on the phone has told you chat couldn't handle their problem.
Are your QA scores consistent between reviewers?#
Probably not, unless you calibrate. Several reviewers scoring tickets will score differently, so an agent can look weak because they drew a strict reviewer, and another can look like a star thanks to a lenient one.
Once a month, have every reviewer score the same 5 to 10 tickets on their own, then compare and talk through the gaps. Track how often scores land within a point of each other. Our working target is above 80% agreement; below that, the QA data shouldn't drive performance decisions. Rotate who reviews whom, too. Our customer service QA playbook has the full calibration routine.
Is QA sampling enough?#
Usually not. Zendesk says only about 2% of support conversations are reviewed manually (Zendesk, checked October 2026). Do the maths on a typical month. From 5,000 conversations, your QA team looks at about 100. Even with perfectly random sampling, a pass rate from 100 conversations carries a margin of error of about ±10 points at 95% confidence. Your 82% could be 72% or 92%.
And the sample is rarely random. Reviewers drift to problem tickets, new agents and last week. So teams coach on samples too small to mean much and miss problems that never get picked.
Automated scoring changes the coverage. A tool that scores every conversation against the same criteria gets rid of the sampling gap, though it catches patterns better than edge cases, so you still read conversations. The question shifts from "is our quality okay?" to "which situations, agents, days and customer types produce the problems?"
Which KPIs matter most for ecommerce support?#
Ecommerce support is high-volume, order-centric and close to revenue, so three extra numbers earn their place. How well you resolve order-status questions, whether customers who contacted support buy again, and what each kind of resolution is worth. The first is usually your biggest single ticket type, and the other two tie support to money.
WISMO Resolution and Self-Service Deflection#
WISMO ("Where is my order?") is usually the biggest single category in an online store's queue, and the most automatable. The metric worth tracking is how many WISMO conversations end with the question settled and no repeat contact, rather than how many got pushed to a tracking page.
Self-service is cheap. Gartner found live channels cost an average of $8.01 per contact against about $0.10 for self-service (Gartner, 2019 data). But self-service on its own doesn't finish the job. In 2024 Gartner reported that only 14% of service issues are fully resolved in self-service, and only 36% even for issues customers called "very simple" (Gartner, 19 August 2024).
That's the gap between ticket deflection and resolution. A tracking link sent to someone on day six of a three-day delivery counts as deflected. They've already seen the tracking page. What they want to know is whether the parcel's lost, so they ask again on another channel and now you've got two tickets. (If your self-service numbers look fine and the queue doesn't shrink, the reason is usually structural rather than the content.)
So track two numbers. WISMO's share of total volume tells you whether your shipping notifications are doing their job. The share of WISMO conversations with no follow-up within 48 hours tells you whether the answers were any good. High share: fix notifications before you hire. Lots of repeats: whatever answers the question can't see enough of the order.
Do customers who contact support buy again?#
They can do so more often than customers who never needed help, if support is good. A problem fixed quickly is proof you stand behind what you sell. If your support-contacted customers buy again less often, support is making things worse.
To check, compare 90-day repeat purchase rates for customers who contacted support against those who didn't, controlling for order value, product category and how long they've been customers. The controls matter. Customers who contact you may simply be more engaged with your brand, so compare like with like. The gap tells you whether support is a net plus or minus for retention.
What is each resolution worth?#
Most stores know cost per ticket. Far fewer know what a resolution is worth. A conversation that talks a customer into an exchange instead of a return keeps the order and the return shipping. A question that a tracking email would have answered earns nothing.
Tag tickets by outcome (return prevented, order saved, cart recovered, upsell, purely informational), then follow the customers' purchases afterwards to put a value on each category. Your own numbers will beat any benchmark here, and they'll tell you which ticket types deserve a fast, careful human and which should be automated hard.
How do you measure an AI support agent?#
Measure it the way you'd measure a new hire: how much it resolves, how much it hands over, and how many of its "resolved" conversations come back. The trap is the AI's resolution rate on its own. Customers who give up look the same as customers who got their answer, so a repeat-contact check is what makes the number honest.
Containment is the number most vendors sell on: the share of conversations finished without a person. Check it the same way as FCR. Of the conversations the bot "finished", how many customers came back about the same thing within 48 hours? Subtract them and you've got something closer to a real resolution rate.
Then look at the handoffs. A bot that never hands over is guessing on the hard cases, and customers want the option. Gartner's 2026 survey of 3,566 customers found 87% say it's essential to be able to reach a human agent when a company uses GenAI for service (Gartner, 4 August 2026). Read the escalations weekly. Each one is either a case that genuinely needed a person or a gap (a missing doc, a playbook without the right step) you can close.
In Hay.chat the raw material sits in a few places. The dashboard's resolution rate is the share of conversations marked resolved, and a conversation where the customer goes quiet is closed and marked resolved after 30 minutes. So read it as containment and check repeat contacts beside it, which is exactly the habit this post argues for. Next to it, a human escalations widget shows handoffs today and this week, and conversations waiting for a person sit in Needs Attention. Hay.chat scores its confidence on answers that make claims about your business and hands the conversation over when the score is low (under 0.5 by default), so the escalation count doubles as your list of gaps. Your team can also rate individual AI replies good or bad, which gives you a quality log without sampling. (Our post on preventing AI hallucinations has a weekly review routine for exactly this.) If you'd rather see those numbers on your own store's conversations, Hay.chat has a 30-day free trial and doesn't ask for a card.
How many customer service KPIs should you track?#
Five on the daily dashboard, and everything else in a weekly report. Competitors' guides say four to six or five to ten, so the number isn't the clever part. The point is that each of the five predicts an outcome, each has an owner, and anything that can't change what you do tomorrow doesn't get a slot.
The 5-metric rule#
Why five? Partly attention. George Miller's famous 1956 paper put short-term memory span at "seven, plus or minus two" items, and later work by Nelson Cowan put the real working-memory limit nearer four (Miller, 1956; Cowan, 2001). Neither study is about dashboards, so I won't pretend they prove the rule. But anyone who's sat through a fifteen-metric stand-up knows the pattern: add a sixth number and the first five get less attention, add a tenth and none of them gets enough to trigger action.
So here's the five I'd put up, and how often to look.
| KPI | What it predicts | Leading or lagging | Review | Starting target |
|---|---|---|---|---|
| Customer effort score | Loyalty | Leading | Daily, by issue type | 70 to 80% answering 5+, 90% excellent |
| First contact resolution | Cost and satisfaction | Leading | Weekly | Your own trend; SQM calls 70 to 79% good |
| Repeat contact rate | Resolutions that didn't stick | Leading | Daily | Investigate above about 20% |
| Time to resolution by complexity | Operational health | Lagging | Weekly, median per tier | Simple <10 min, moderate <4 h, complex <48 h |
| One business metric | Revenue impact | Lagging | Monthly | Ecommerce: support-influenced repeat purchase. SaaS: escalations to engineering |
CSAT distribution, escalation rate and utilisation belong in the weekly deep-dive. They matter. They just don't need to be in front of you every morning, and putting them there takes attention from the five that do.
Leading vs. Lagging Indicators#
Leading indicators move before the outcome. Lagging ones confirm it afterwards. CES and repeat contact rate are leading: rising effort or repeats shows up before cancellations do. Retention, NPS and revenue recovered are lagging. They tell you whether it worked, after the fact.
A dashboard of lagging indicators tells you what happened. Leading ones tell you what's about to, which is the only moment you can still do something. That's why the table above leans three to two in favour of leading. Look at the leading ones daily, the lagging ones weekly or monthly.
Review Cadence#
Daily: what needs action now. Queue depth, response time, staffing, and any leading indicator that's suddenly moved.
Weekly: quality trends. FCR, repeat contacts, escalation patterns, CES by channel. You're looking for which way things are heading. One bad day is noise.
Monthly: outcomes that need bigger samples. Retention impact, NPS, cost per resolution, revenue by ticket category.
Quarterly: the framework itself. Are these still the right five? The KPIs that matter in hypergrowth (volume, speed to scale) aren't the ones that matter when you're chasing profit (cost per resolution, automation rate), so revisit them when the business changes.
Retention is why all of this is worth the effort. Bain's Frederick Reichheld found that raising retention by 5% raises profits by 25% to 95%, and winning a new customer costs anywhere from five to 25 times more than keeping one, "depending on which study you believe" (HBR, October 2014). Support sits in the middle of both.
Frequently asked questions
Want to see what an AI agent resolves in your store?#
Connect your store and let Hay.chat take the order questions, and the refunds your playbooks call clear-cut. Its dashboard puts the resolution rate next to every escalation, and you can open any conversation behind either number. You get 30 days free, and there's no credit card to enter. After that, plans start at €50 a month with 500 resolutions included.
Sources#
All pages checked 21 October 2026.
- Matthew Dixon, Karen Freeman and Nicholas Toman: Stop Trying to Delight Your Customers, Harvard Business Review, July 2010
- SQM Group: FCR metric operating philosophy, updated 20 August 2026, and FCR benchmark results by industry, February 2025
- Zendesk: CX Trends 2026, November 2025
- Zendesk: Customer service scorecard (the 2% manual review figure)
- Gartner: press release on self-service and contact costs, 25 September 2019
- Gartner: only 14% of service issues fully resolved in self-service, 19 August 2024
- Gartner: 87% of customers want access to a human agent, 4 August 2026
- Amy Gallo: The Value of Keeping the Right Customers, Harvard Business Review, 29 October 2014
- ICMI: How Busy is Too Busy?, 2012
- George A. Miller: The Magical Number Seven, Plus or Minus Two, Psychological Review, 1956
- Nelson Cowan: The magical number 4 in short-term memory, Behavioral and Brain Sciences, 2001
- Hay.chat: dashboard and analytics documentation
Ask AI about this page
About the Author

Damien Mulhall
Co-Founder, Strategy and Content
Damien spent 10+ years managing support operations and project delivery for global brands including Dell, Microsoft, Intel, and Google. He's PMP-certified, and that operations background shapes how Hay.chat is built.
Related posts
-
Why Your FAQ Page Isn't Reducing Support Tickets

-
Scale Support Without Burning Out Your Team
-
Insights: see what your AI gets wrong, and what to fix